Ingestion-first, not a demo
LlamaIndex development services: production-grade RAG and data ingestion
LlamaIndex is the leading framework for connecting LLMs to your private data: chunking, embedding, indexing, and retrieving with precision. I build this correctly: ingestion-first pipelines that survive real-world data drift, not a fragile demo that breaks on the first messy PDF.
Honest read included: whether LlamaIndex is even the right ingestion engine for your data.
Ingestion: Load & Parse
Extract text, tables, and metadata from documents
Plain answer
What is LlamaIndex?
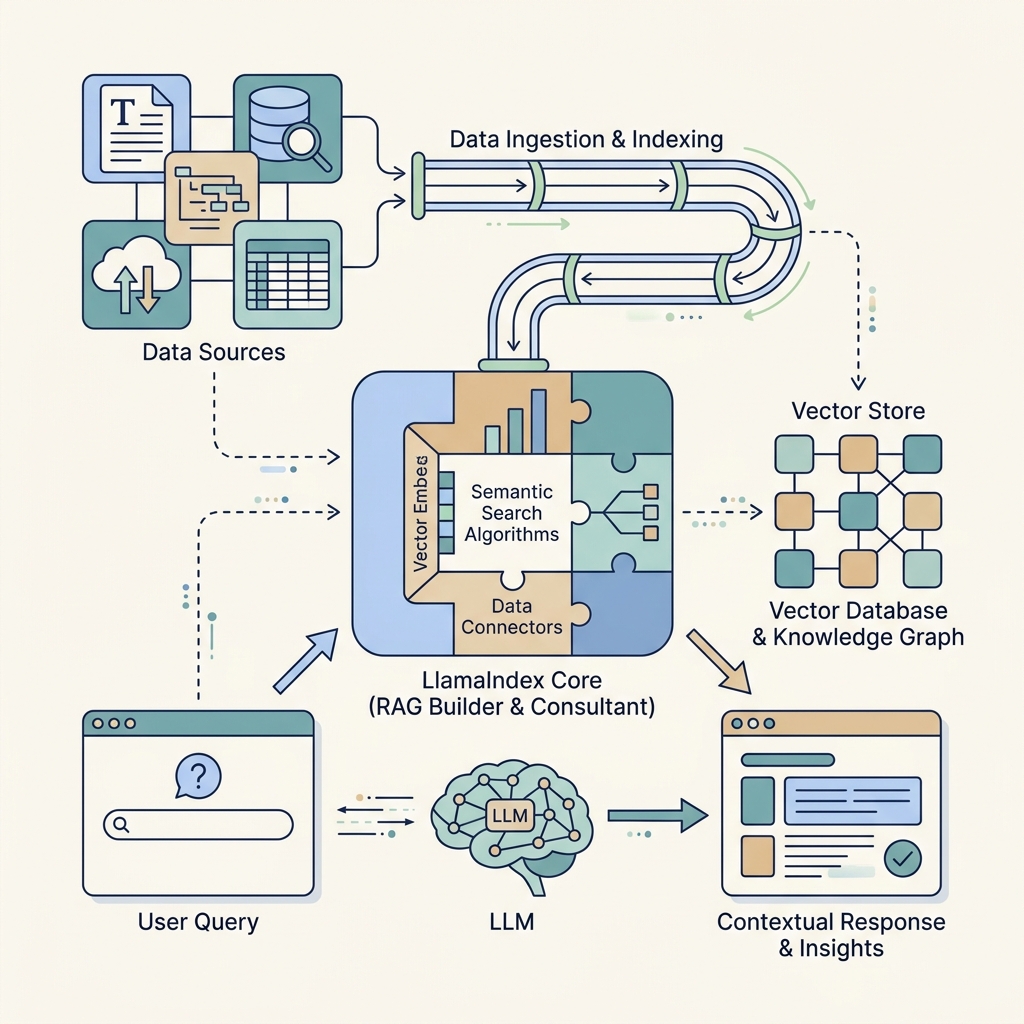
LlamaIndex is an open-source data framework for building LLM applications that require custom ingestion and retrieval. It provides connectors for over 150 data sources, configurable chunking and indexing strategies, and a query engine with hybrid search, reranking, and structured output. LlamaIndex is the leading framework for production RAG systems, with a strong focus on data pipeline integrity and retrieval accuracy.
What I build
LlamaIndex development services
Ingestion pipeline architecture
Custom document ingestion pipelines using LlamaIndex's node parsers, text splitters, and metadata extractors to prepare your data for high-quality retrieval.
RAG pipeline development
Retrieval-augmented generation pipelines that prioritize retrieval quality through advanced indexing strategies, hybrid search, and re-ranking.
Advanced retrieval system design
Production retrieval systems with custom embedding models, vector store integration, and query transformation for consistent, relevant results.
Structured data extraction & indexing
Systems that extract key information from unstructured documents and index it for precise querying across your knowledge base.
Retrieval quality & performance audit
Review of your existing retrieval pipeline, identifying bottlenecks in chunking, embedding, or retrieval routing to improve accuracy and latency.
Hybrid search & re-ranking implementation
Integration of keyword and vector search with cross-encoder re-rankers to boost retrieval precision beyond simple semantic similarity.
Get an honest assessmentThe honest comparison
LlamaIndex consultant vs LlamaIndex agency
| Factor | Independent LlamaIndex consultant (me) | LlamaIndex development agency |
|---|---|---|
| Cost | Lower, direct rate, no team overhead | Higher, includes team and account management |
| Who builds it | Me, directly, every time | Allocated team member, may change |
| Best for | Scoped ingestion pipelines and RAG builds, $3K to $40K range | Large, multi-pipeline product builds with ongoing data ops |
| Start time | 48 to 72 hours | 2 to 4 weeks typically |
Most LlamaIndex projects—a specific ingestion pipeline, a custom retrieval strategy, a connector integration—are well within scope for a single experienced developer working directly with you. An agency's advantage shows up when a project genuinely needs several specialists handling parallel data streams, UI, and DevOps, not for the LlamaIndex engineering itself.
How we work together
Engagement models
Fixed-price, milestone-based
A scoped LlamaIndex build delivered as a fixed-price, milestone-based engagement.
Consulting
Architecture review or debugging support for an existing implementation.
Dedicated monthly
Ongoing LlamaIndex development for businesses with a continuing retrieval AI roadmap.
Build Flow
Process
PHASE 01days 1 to 2
Discovery & Ingestion
+
PHASE 02within 48h
Retrieval Architecture Spec
+
PHASE 03the decisive one
Milestone Build
+
PHASE 04before launch
Evaluation & Tuning
+
PHASE 05handoff
Deployment & Monitoring
+
Honest Tool Fit
When LlamaIndex is not the right choice
Direct architectural honesty upfront
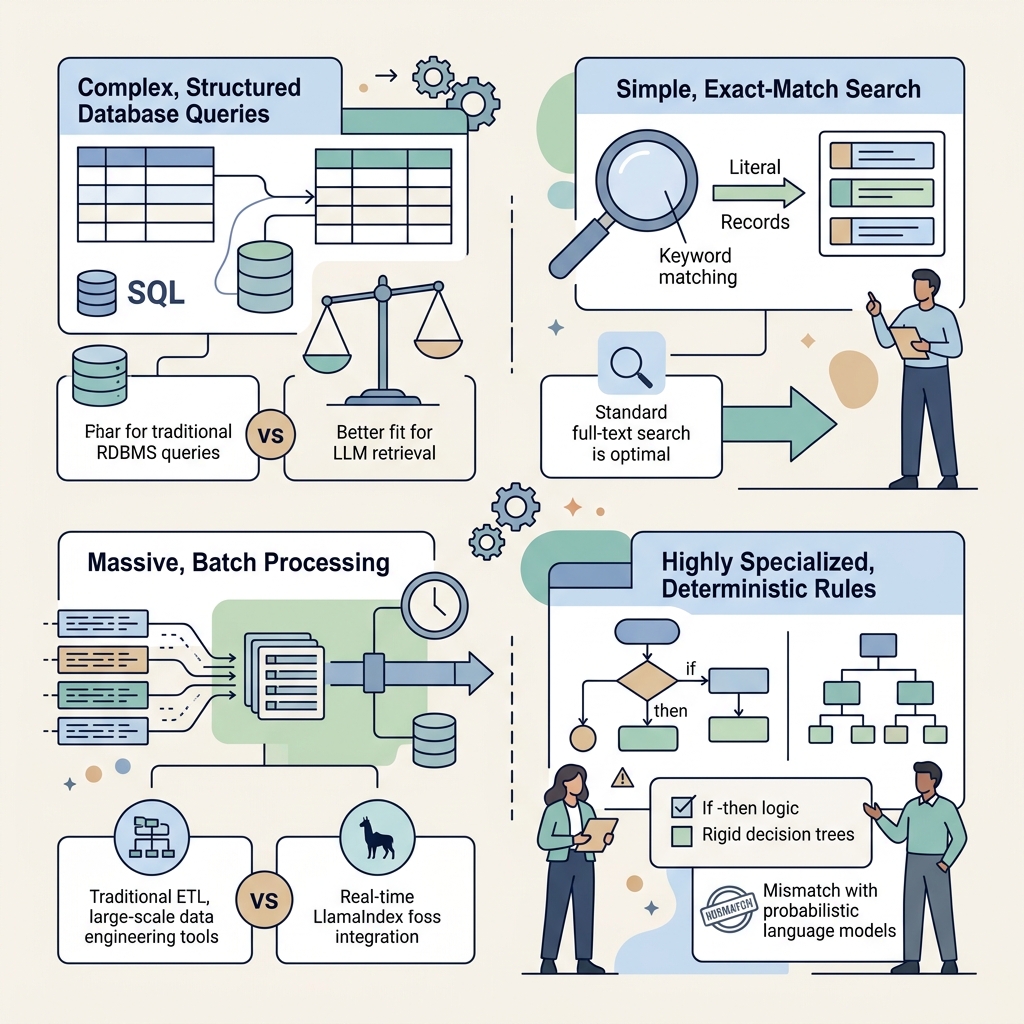
Part of a proper LlamaIndex engagement is an honest assessment of whether it's even the right tool for your specific problem. If your actual need includes multi-step agentic behavior with complex tool chains and state management, a LangChain-based approach may offer a more suitable abstraction. See the LangChain development services page for the fuller comparison.
Investment
Engagement Options
| Engagement type | What's included |
|---|---|
| Single data source ingestion Free | One scoped ingestion pipeline with chunking and embedding to vector store |
| Full RAG system | Multi-source ingestion, advanced retrieval (hybrid, recursive), query engine, guardrails |
| LlamaIndex system audit | Review and tuning plan for an existing LlamaIndex deployment |
| Hourly consulting | Architecture review, retrieval optimization, debugging support |
Retrieval and generation-grounded systems built using this class of architecture include the AI Customer Feedback Classification pipeline and AI Video Summarizer. Full case studies at shreyans.tech/ai-case-studies.
FAQ