Data Labeling: Why It's the Hidden Bottleneck in AI Projects
A classifier stops improving. The team tries a bigger model, more epochs, better hyperparameters. Nothing moves. The actual cause was upstream: inter-annotator agreement of 0.62, meaning the humans producing the ground truth disagreed with each other roughly a third of the time. The model was being asked to resolve a contradiction, and no architecture can do that.
This is why the data labeling process is the most consequential and least examined stage of most AI projects. It gets discussed as a cost line and a scheduling problem, when the more important fact is that it silently sets the ceiling on everything built above it.
Labels Aren't Data Entry, They're Ground Truth
The framing that causes the damage is treating labelling as throughput: a volume of items to be processed as cheaply as possible. Under that framing, the optimisations are obvious and wrong, pay per item, hire more annotators, ship faster.
What labelling actually produces is the definition of correctness that the model will be optimised against and evaluated on. If that definition is inconsistent, two things happen at once: the model learns noise during training, and your evaluation metric stops measuring what you think it measures. A model scoring 90% against ground truth that humans only agree on 80% of the time is partly being scored on coin flips.
And the disagreement is often not carelessness. A published benchmark on dermatology image label errors measured agreement between qualified experts at 0.42, below the conventional reliability threshold. When specialists disagree that much, the ambiguity is intrinsic to the task, and no amount of annotator discipline resolves it. It has to be resolved in the guidelines.
Hire Edge Computer Vision
The Process, Step by Step
A defensible labelling operation runs the same sequence regardless of data type.
|
Step |
What happens |
Why teams skip it |
|---|---|---|
|
1. Draft guidelines |
Define each label, including edge cases and decision rules |
Feels obvious until two people read it differently |
|
2. Pilot on a small batch |
Multiple annotators label the same items independently |
Seen as delay; it is the cheapest error-detection available |
|
3. Measure agreement |
Compute inter-annotator agreement before scaling |
Nobody asks for the number, so nobody produces it |
|
4. Revise guidelines |
Fix the definitions the pilot proved ambiguous |
Teams add QA instead, treating the symptom |
|
5. Build a gold set |
Expert-adjudicated items used to score annotators continuously |
Requires expensive expert time up front |
|
6. Annotate at scale |
Production labelling with gold tasks seeded into queues |
— |
|
7. Adjudicate and iterate |
Resolve disagreements; feed edge cases back into guidelines |
Treated as one-off rather than continuous |
Steps two and three are where projects are won or lost, and they're the two most often compressed to save a week. Running a labelling pilot before committing to full volume is the same discipline as running a feasibility pilot before committing to a full build, building an AI PoC makes the equivalent case at project level.
Hire Edge Computer Vision
The Number That Predicts Everything
Inter-annotator agreement, measured with Cohen's kappa or Krippendorff's alpha, is the single most useful metric in this whole process, and most teams never calculate it.
|
Metric |
Healthy threshold |
What a miss means |
|---|---|---|
|
Inter-annotator agreement |
Above 0.8 |
Below this, your guidelines are ambiguous |
|
Rework rate |
Under 15–20% |
Higher suggests unclear instructions or unsuitable annotators |
|
Ground truth accuracy |
Above 0.9 |
Your gold set itself may be unreliable |
The crucial interpretation: when agreement drops below 0.8, the correct response is clarifying the instructions, not adding more QA stages or replacing annotators. Practitioners consistently report that investing disproportionately in guideline development, with visual examples, decision trees, and worked edge cases, delivers larger quality improvements than layering on additional review. Low agreement is a specification failure that presents as a staffing problem.
What Works and What Fails in Annotation QA
|
Works |
Fails |
|---|---|
|
Multi-annotator consensus to build gold standards, then refining instructions from the disagreements |
Over-relying on automation without manual validation |
|
Multi-layer QA combining self-review and targeted spot checks |
Majority voting on subjective tasks, which averages away legitimate ambiguity |
|
Active learning to route high-uncertainty samples to human review |
Paying per task rather than per hour, which pays for speed over accuracy |
The pay structure point deserves emphasis because it's so easily overlooked in procurement. Per-item pricing creates a direct financial incentive to label quickly rather than correctly, and that incentive operates on every ambiguous item, which are exactly the items that determine model quality.
The Rare Class Problem
There's a structural trap in any domain where the thing you care about is uncommon. Defect detection, fraud, rare disease, safety incidents: the healthier the process, the fewer positive examples exist to label.
This means annotation volume and annotation value diverge sharply. Labelling a hundred thousand normal items adds little; labelling two hundred genuine edge cases can transform the model. Random sampling is close to the worst possible strategy here. Targeted sampling, guided by model uncertainty, is what makes the budget go further, and in the extreme the answer is to avoid needing defect labels at all, which is why computer vision in manufacturing and similar domains increasingly lean on approaches that train on normal examples alone.
How the Pipeline Looks in 2026
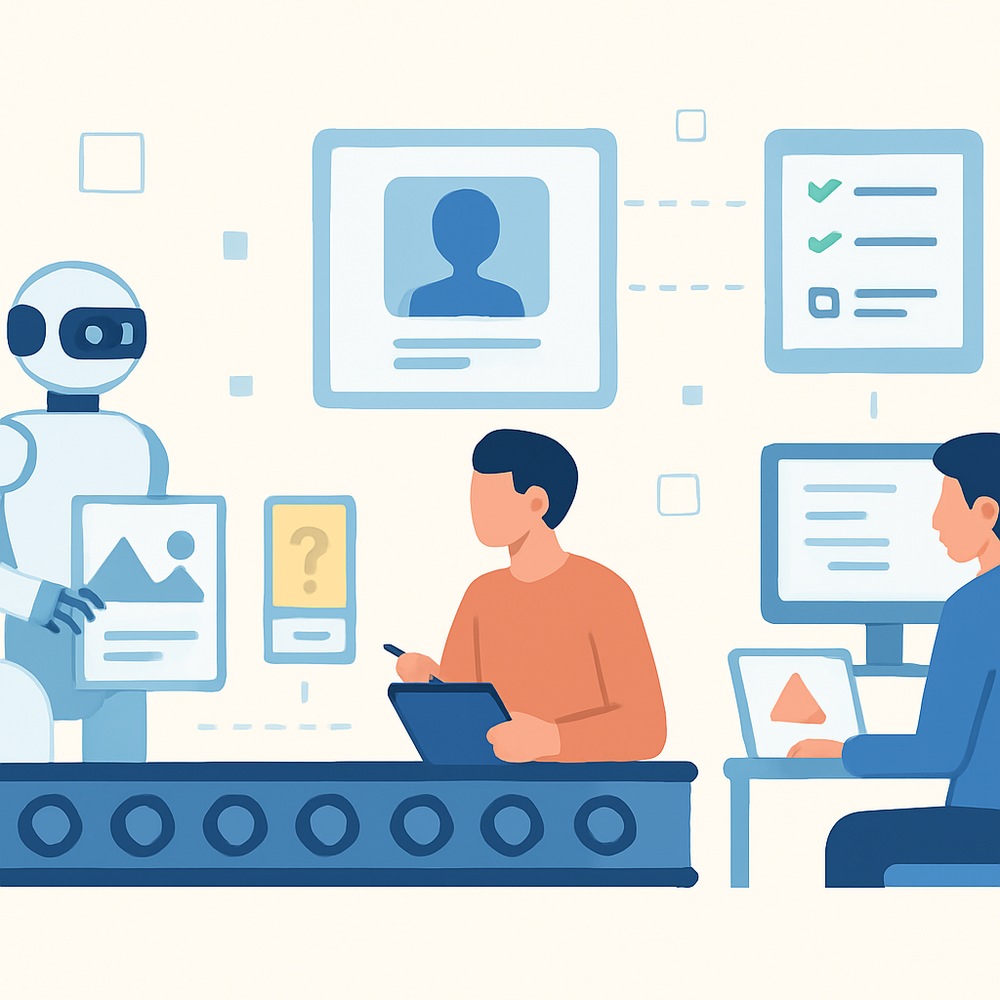
Labelling has stopped being a one-time preparation task. The current pattern is a continuous pipeline: production traces flow back in, a model auto-labels the high-confidence cases, ambiguous items route to humans, and everything is written to a versioned dataset with full provenance.
Hybrid auto-labelling works when it's validated rather than assumed. One published approach applied a high-confidence auto-labelling rule to the bulk of a dataset and reserved roughly 10% for manual annotation, verifying on a held-out sample that the automatic labels agreed with human annotators. The discipline that makes this safe is the verification step, not the automation.
Two things to build in from the start rather than retrofit. Provenance: who labelled each item, when, under which version of the guidelines, and who reviewed it, because that is what an auditor will ask for and a spreadsheet cannot answer. And compliance metadata, privacy flags and PII handling, captured at the labelling stage, since retrofitting consent and anonymisation records onto an existing dataset is considerably harder than recording them as you go.
Who Should Actually Label
The choice is usually framed as cost per item, which is the wrong axis. The right question is how much domain judgement each item requires.
Tasks with objective, easily specified answers suit crowdsourced or managed annotation workforces well. Tasks requiring professional judgement, a clinical finding, a legal clause, a manufacturing defect classification, need domain experts, and using cheap annotators on them produces a dataset that looks complete and encodes the wrong answers. A workable middle path is experts writing the guidelines and adjudicating disagreements while a broader workforce handles volume. Annotation tooling experience is worth screening for explicitly in anyone you engage for this, and vetting a CV consultant covers it among the other competencies that separate production experience from tutorial familiarity.
Hire Edge Computer Vision
Frequently asked questions
Why is data labeling considered a bottleneck in AI projects?
What is inter-annotator agreement and what score should I aim for?
How do I improve labeling quality if agreement is low?
Can AI automate the data labeling process?
Should I pay annotators per item or per hour?
How much labeled data do I need?


Shreyans Padmani
Shreyans Padmani has 5+ years of experience leading innovative software solutions, specializing in AI, LLMs, RAG, and strategic application development. He transforms emerging technologies into scalable, high-performance systems, combining strong technical expertise with business-focused execution to deliver impactful digital solutions.